We started by getting blocked.
Scrape.do was established in 2020 as a web scraping API for unblocked access to public web data. One request returns the page you ask for, with proxies, CAPTCHAs and anti-bot blocks handled for you, and you pay only for successful requests.
- GET/products?page=2403Forbidden
- GET/products?page=2403Forbidden
- GET/products?page=2429Too Many Requests
- GET/products?page=2200OK
The first three lines are why Scrape.do exists.
- Blocked at the wall
- 403 and 429
- 200 OK through Scrape.do
The story
Scrape.do started in 2020 in Türkiye as one developer, our founder Batuhan, and a tool built to get past the blocks that kept stopping scraping jobs.
We turned that tool into infrastructure other teams could rely on.
It began as a tool I built for myself. I was doing freelance scraping projects on the side and kept getting blocked, so I wrote something that didn't get blocked.
Customers all over the world
Soon Scrape.do had users all over the world.
By May 2025, Scrape.do was handling 500M requests a day, and with our increasing number of users and the AI boom, we now handle 10B+ requests a month for 10,000+ users.
No investors, no outside money. Just customers who needed data and a product that got it for them.
From one desk to a team
Today we're a team of 25+. The one-person company had grown fast with top talent, 70% of them in technical roles. The people who build Scrape.do also answer its support tickets, with an average response under 5 minutes.
Latest news
The team keeps shipping. Launches and company news from the last year, newest first.
-
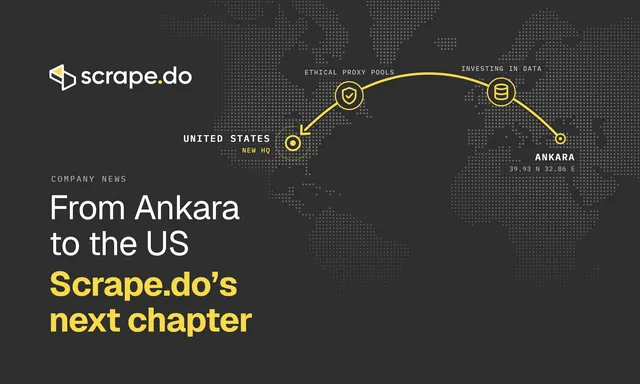
Scrape.do moves its headquarters to the US
-
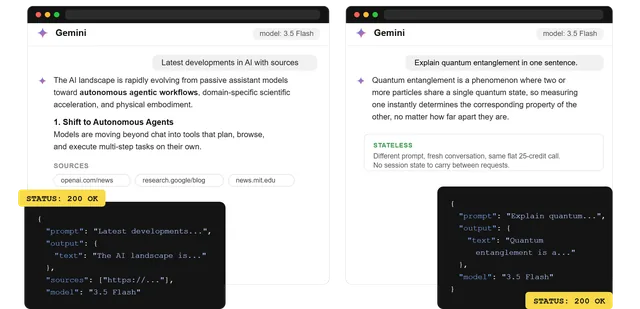
Gemini API, with the sources each answer cites
-
Teams arrive in the dashboard
-
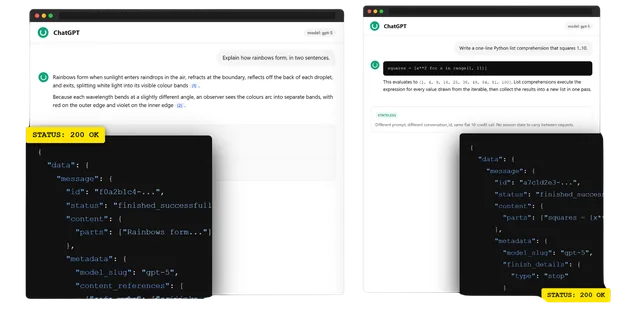
ChatGPT API: one prompt in, the reply as JSON
-
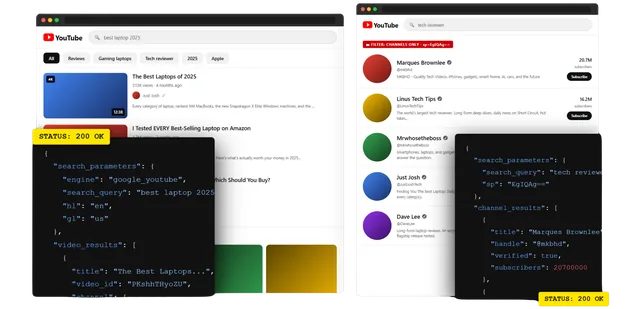
YouTube API for videos, channels and Shorts
-
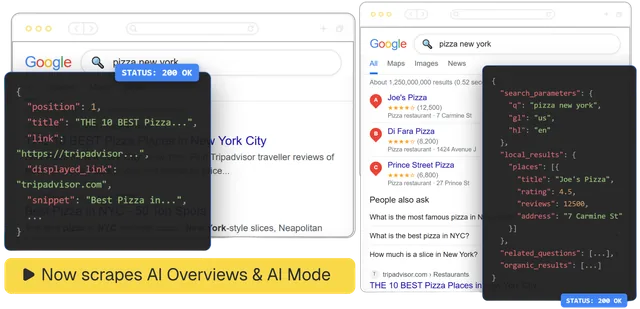
SERP API now covers AI Overviews and AI Mode
-
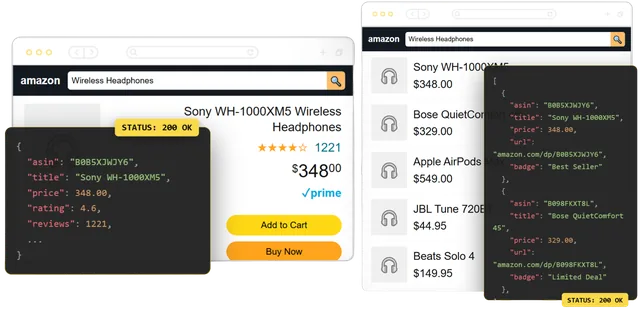
Amazon Scraper API: products, search and reviews
-
Scrape.do v2 is live
Build it yourself, or send one request
On your own
You build it and keep it running:
- Rotating proxies
- Headless browser rendering
- CAPTCHAs and anti-bot blocks
403When a block wins, the door shuts.
With Scrape.do
You send one request. Handled for you:
- Rotating proxies
- Headless browser rendering
- CAPTCHAs and anti-bot blocks
200The page comes back, and you pay only for successful requests.
What is Scrape.do?
Scrape.do is a web scraping API: one request returns the page you ask for, with proxies, CAPTCHAs and anti-bot blocks handled for you. Developers, data teams and AI builders use it for unblocked access to public web data at scale, and pay only for successful requests.
What we provide
- Web Scraping APIAny page, one request.
- Ready-made scraper APIsGoogle, Amazon and more, as data.
- Async APIBig batches, run in the background.
- ScrapemanOur free, open-source API client.
Founded in 2020, Scrape.do is headquartered in the United States and operated by PACKEND, LLC.
Industries we serve
What teams in nine industries collect with Scrape.do, each with its own page.
- E-commerce
- AI and LLM
- Travel
- Real estate
- Marketing
- Social media
- Finance
- Cryptocurrency
- Job boards
Plus 52 site-by-site scraper pages, such as Nike, Funda and Hilton.
A note from the founder
That is Scrape.do today. Batuhan's note says where we are going next.
Accessing honest, accurate data is going to get harder.
More of the web is sitting behind walls,
more of it is being written by machines,
and more of the decisions made on top of it are being made by AI.
We want Scrape.do to have a part to play here: in powering the AI ecosystem, in keeping the web open for the people building on it, and in shaping where technology goes next.
The problem is bigger now, the stakes are higher, and the web needs companies that do this the right way.
In the press since 2025
The latest first, from an AMA with the team in September 2026 back to a founder interview in May 2025.
- 2026
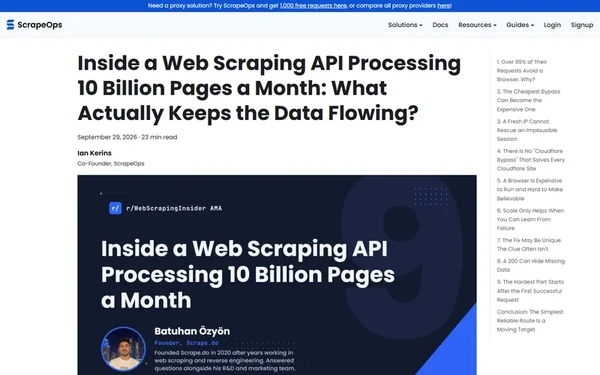
Inside a Web Scraping API Processing 10 Billion Pages a Month: What Actually Keeps the Data Flowing?
-
How to Scrape Difficult Websites at Scale: Inside a Web Scraping API Processing 10B+ Pages a Month | AMA with Batuhan from Scrape.do
-
Best Proxy Providers in 2026, Based on 9 Billion Pages per Month
Best Value Web Scraping API
-
Scrape.do Launches New SERP API With Full Google Search Coverage, Including AI Overviews and AI Mode
-
Most "Smart Proxy" Scraping APIs Fail Browser Fingerprinting Tests [January 2026]
2nd of 10, score 81.43
- 2025
The Web Scraping Insider #3 - Proxy Costs, GenAI & Paywalls
Amazon.com, June 2025 data
Top value performer
-
How Scrape.do Scaled from Side Project to 500M Daily Requests - Founder Batuhan Özyön Shares the Journey


Ranked by others
ScrapeOps publishes The Web Scraping Insider and hosts the r/WebScrapingInsider AMAs. As its write-up says, it routes a significant amount of traffic through Scrape.do.
Awards from our users’ reviews
Capterra and Software Advice give these badges from what users write in their reviews.
 Best Ease of UseCapterra, 2025
 Best ValueCapterra, 2024
 Best Customer SupportSoftware Advice, 2025
 Front RunnersSoftware Advice, 2024
 Most RecommendedSoftware Advice, 2025
Ratings
As each platform showed them on September 30, 2026.
- 4.8TrustScore on Trustpilot
- 5.0out of 5 on Capterra49 reviews
- 5.0out of 5 on G25 reviewsSource: G2.com, Inc.
The badges from Capterra, GetApp, and SoftwareAdvice are trademarks and service marks of Capterra, Inc., Nubera EBusiness S.L., Software Advice, Inc. and/or its affiliates (collectively, “Badge Entities”), and are used herein with permission. All rights reserved. The badges constitute the subjective opinions of individual end-user reviews, ratings, and data applied against a documented methodology; they neither represent the views of, nor constitute an endorsement by, the Badge Entities.
Every IP, ethically sourced
Residential proxies run on real people's connections. In 2026, two residential proxy networks built on hijacked devices were disrupted. Here is where we stand.
"Our position hasn't changed: every IP in Scrape.do's proxy network is 100% ethically sourced, and it always has been."
Where our IPs come from
- Carefully vetted sources
We vet where the IPs in our proxy network come from.
- Our own proxy pools
We run them ourselves, so we know exactly where every IP comes from.
- Built for public data. Scrape.do is a toolkit for collecting public data at scale, and our guide covers when web scraping is legal.
- Lawful use only. Card testing, fake account creation, vulnerability scanning, credential cracking and account takeover end in immediate suspension. Terms of Use
F.A.Q
Questions about Scrape.do
Short answers to the questions people ask about Scrape.do.
Not on the list? Ask an engineer at support@scrape.do: the average response time is under 5 minutes.
Batuhan Ozyon founded Scrape.do in 2020 and still leads it as founder and CEO. It started as a tool for his own freelance scraping projects, which kept getting blocked. A large company heard about it by word of mouth and became the first customer within a week.
Scrape.do was founded in Türkiye in 2020. It is now headquartered in the United States, after the move Batuhan announced in September 2026. The company behind it is PACKEND, LLC.
Developers, data teams and AI builders who need public web data at scale: search results, maps listings, product pages and prices. Teams at Revolut, TripAdvisor and Expedia use it.
With credits, and only for successful requests. Timeouts, blocks and errors cost nothing. Every account gets 1,000 free credits a month, no card needed.
Yes. You can cancel, downgrade or upgrade whenever you need, from your dashboard. A first subscription can be refunded within 3 days of purchase, for the credits you have not used.
Engineers, 24/7, at support@scrape.do. The average response time is under 5 minutes, and every paid plan includes real developer support: no bots.
Yes. Every IP in Scrape.do's proxy network is 100% ethically sourced, and Scrape.do may be used only for lawful purposes. The ethics section above has the details and the sources.
Collecting publicly available data is legal in many cases, but it depends on the data, the website's terms and the law where you operate. Scrape.do is built for public web data. Our guide on web scraping legality walks through the main cases.