# Scrape Prices and Availability from Nordstrom
> Source: https://scrape.do/industries/ecommerce/nordstrom-scraper/
Extract product prices, markdowns, and availability from Nordstrom at scale. Scrape.do clears the Kasada JavaScript challenge automatically.
**Scrape Prices and Availability from Nordstrom**
Extract product pricing, markdowns, size and color variants, and stock status from one of the largest US upscale department stores. Nordstrom sits behind Kasada, which serves a JavaScript challenge and blocks datacenter proxies. Scrape.do handles it automatically.
## How to Scrape Nordstrom
### Product Page
Extract product data from any Nordstrom product page with a single API call.
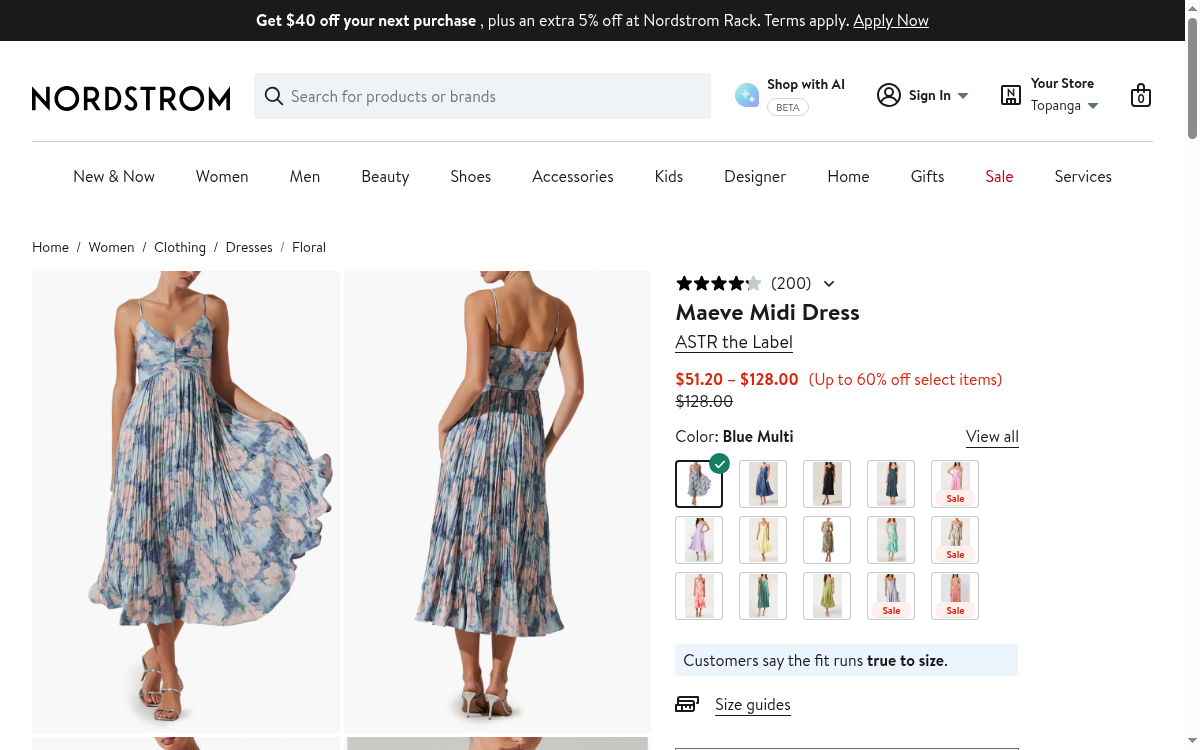
**Example response**
```html
ASTR the Label Maeve Midi Dress (Women) | Nordstrom
```
Scrape **Nordstrom** (https://www.nordstrom.com) and receive the data as structured JSON.
**Example extracted fields**
| Field | Example |
| ----- | ------- |
| Price | $51.20 |
| Availability | In Stock |
| Brand | ASTR the Label |
| Rating | 4.2 ★ (200) |
### 31M Monthly Visits. Every Brand. One API.
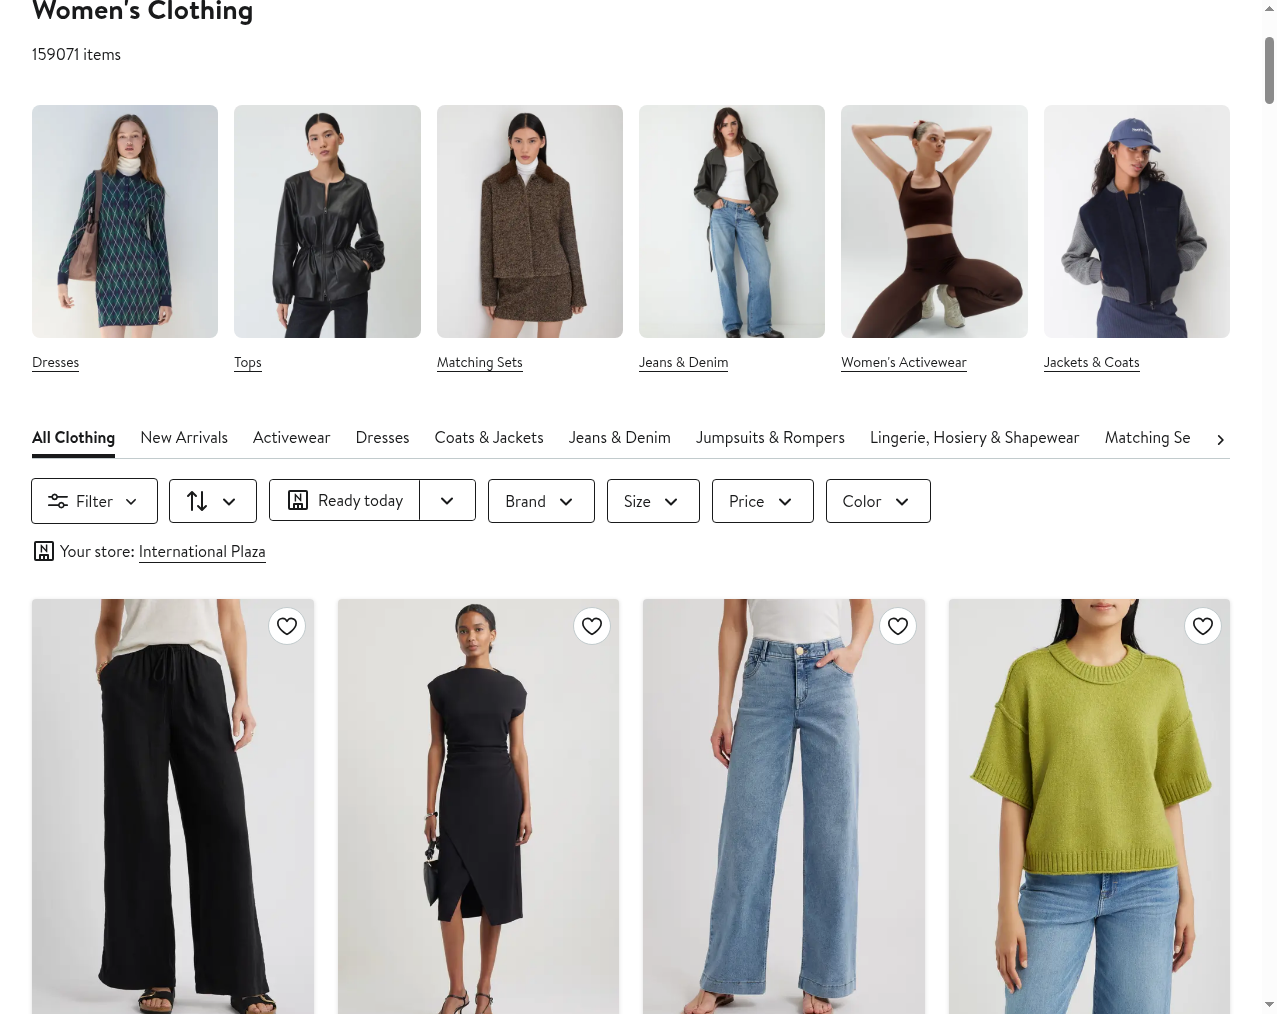
Nordstrom is a **major US upscale department-store retailer**, drawing **over 31 million monthly visits** across designer, contemporary, and off-price Nordstrom Rack assortment in fashion, shoes, beauty, and accessories. Its mix of full-price and steep markdown pricing across premium brands carries the sale cadence, variant availability, and ratings that fashion price-intelligence scrapers track.
With Scrape.do you can **track upscale fashion pricing and markdowns**, compare against Saks, Macy's, and Bloomingdale's, **monitor brand and assortment coverage**, and capture size, color, and stock availability. All through a single API call.
### Kasada. JavaScript Challenge. Handled.
Nordstrom sits behind **Kasada**, fronted by Fastly, which answers requests from Python `requests`, cURL, and datacenter proxies with a blank JavaScript challenge page instead of the real content. The challenge uses heavily obfuscated inline JavaScript with rotating cookie and script names, so a raw fetch returns a 200 with no products, prices, or markdowns, and signature-based scrapers never see the page.
Scrape.do rotates *high-quality residential IPs* with full browser fingerprints, executes the Kasada challenge in a real browser, and renders the JavaScript so you receive fully populated product and category HTML. You get clean pricing, variant, and availability data without maintaining proxy pools or headless browsers.

## FAQ
### Can Scrape.do bypass Nordstrom's Kasada protection?
Yes. nordstrom.com sits behind Kasada, which returns a blank JavaScript challenge page to Python `requests`, cURL, and datacenter proxies instead of the real content. Scrape.do rotates real residential IPs with full browser fingerprints, executes the Kasada challenge, and renders JavaScript to return fully populated product and category HTML. Success rates exceed 95% on product and category pages.
### What data can I extract from Nordstrom?
You can extract product names and brands, current and original prices, markdown and sale badges, size and color variants, stock and availability status, customer ratings and review counts, and full category listings with brand, size, price, and color filters across women's, men's, beauty, shoes, and Nordstrom Rack off-price assortment.
### Do I need to render JavaScript to scrape Nordstrom?
Yes. Nordstrom serves a Kasada challenge and renders product and category details client-side, so a plain request returns a blank page with no prices. Use `super=true` and `render=true` so Scrape.do solves the challenge and executes the page JavaScript in a real browser, and set `geoCode=us` for US pricing and availability.